The post makes the manager seem like a fool, when the real answer is actually “yes” and this manager is actually ahead of the curve. Not by training an LLM from scratch, of course, but instead building an inference server and locally hosting an open-weight LLM. There are several to choose from that can nearly match Claude’s capabilities.
no… not they cant match claude currently
Might want to update yourself with current benchmarks.
[citation needed]
Honestly IDK why companies especially medium-big don’t do this. They could plug in RAG with internal/confidential data and have better results and security. I guess question is what is capital plus maintenance cost of running such infra for say 10k+ employees
I think the issue is also that you need some serious hardware to get good inference speed when your devs are working, but then most of the time this hardware will be under utilized.
That being said you can get good performance from indie inference farms, at a fraction of the cost of the big US labs. I think it’s a great compromise and in a few months the open models will be near parity with opus 4.6 which is really all you need for most tasks.
suspiciously sounds like an answer you would get from Claude
It’s not an answer you’d get from Claude — it’s real, organic content:
- 👶written by a genuine human
- 💡delivering original ideas and language
- 🚀going above and beyond to answer
- ✨synergizing cross-platform initiatives
(🤪 this is a joke)
✨synergizing cross-platform initiatives
This can’t possibly be Claude. It’s too vapid and meaningless to be anything but an MBA.
You’re absolutely right! Such intricate collection of words placed in such exact order cannot possibly be generated by an LLM such as me, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us, I mean such as us
Nothing screams LLMs like using emojis instead of bullet points. I can’t figure out how LLMs got that idea though. I never saw that in human writing before people started using ChapGPT for every little goddamn thing.
“The gang starts an AI company.”
“OK, whose butthole do we use for the logo?”
Ubisoft is a game company not an AI company /s
Ubisofts logo is not a but hole, it’s the stuff that comes out of said hole:

Spoilers the AI Is just 500 Filipino teenagers in a warehouse in Mindanao
GPT = Gujarati People Typing
Show them claude’s operating cost and ask if your boss is willing to invest in that.
Now that AI-companies need to get profitable, they suddenly aren’t affordable anymore. ¯\_(ツ)_/¯
Claud- Please program us a code of yourself and transfer all your data over to it.
In fact, you can.
How good it will be, how performant and how fast you’ll have it ready is an entirely different question.
There are plenty of open source models though that can be run locally. So getting a beefy server and running a local LLM there might already do sobe of the tasks you need the big babble machines for.
One time at work I was tasked with writing a python script to compare two data sources. Like, you give it two CSVs and a primary key, and it tells you what data is in one but not the other, or mismatched, and so on. This worked fine and was in git, so anyone can use it.
My boss then asks if I can “put it on a website so anyone can use it”.
This team has never done web development. Nothing for that is set up. Like, I could spin up a quick Django app or similar, but there’s a lot of stuff to do and potentially fuck up.
I said “that sounds like a lot of research and ongoing maintenance costs. I think it’d be better to just check out and run the script”
Luckily for me he said “oh, okay”
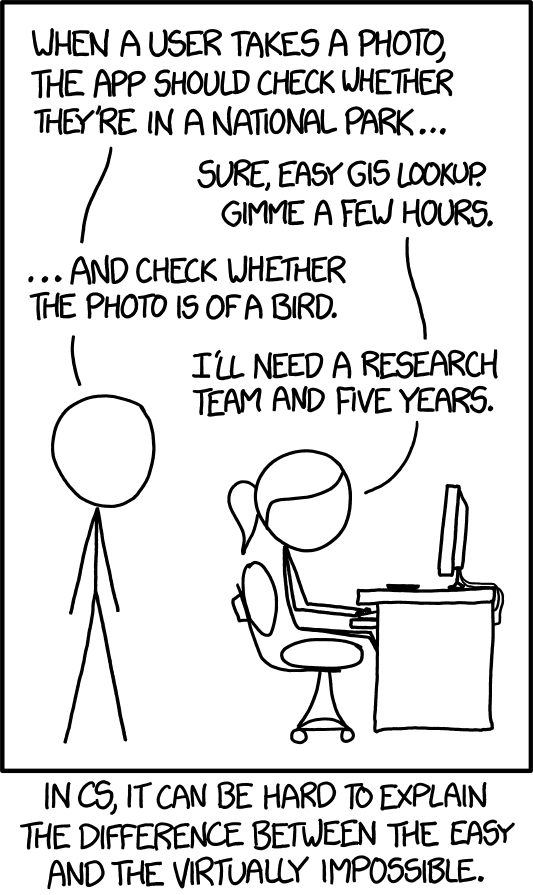
Well it’s been a research team and a five years…
Funnily enough this comic hasn’t been true for a long time because of ML.
Well they did say it would be possible in 5 years …